2021-Jun-20
There’s a meta-contrarian idea that the mechanisms of academia exclude some
really good science that’s just too unconventional. This is not true to the
extent claimed.
Computer algebra is useful but discovering new algorithms to automate
mathematical work is hard.
As Robin Hanson and Steve Levitt say, life is long. There’s lots of time to
do lots of different things.
Juergen Schmidhuber is right: China will surpass
the US in dominance this century.
Here Robin Hanson
proposes a much more efficient method of small claims resolution.
The Enlightenment was about such ideas: approaching economic problems
rationally where previously no one realized there was a problem.
The rapid decision-making abilities of basketball and soccer players impress me
as much as their physical skills.
“Up to 40%” of travelers from developed to developing countries get travelers’
diarrhea; “in the normal population 1% to 2% of persons per year will develop
irritable bowel syndrome (IBS), while 5% to 6% of travelers after traveler’s
diarrhea will develop IBS”; and “the prevalence of depression and anxiety in
IBS patients is 37.1 and 31.4% respectively”.
The Princeton Companion to Mathematics says “algebraists like to work with exact
formulas and analysts use estimates. Or, to put it even more succinctly,
algebraists like equalities and analysts like inequalities”. In computer
science, algebraists like programming languages and analysts like algorithms and
complexity. Or, to put it even more succinctly, algebraists like lambda calculus
and analysts like Turing machines.
During retirement, write a memoir to be read by your descendants
if no one else.
Mathematics, to a first approximation, is a 20th century phenomenon.
2021-Jan-27
One doesn’t discover new lands without consenting to lose sight, for a very long time, of the shore.
-André Gide
One of the things that I often faced in my clinical practice and with the
students that I mentored was this confusion about acting. “I don’t know what to
do, so what should I do? Well nothing, I’ll wait around until I figure out what
to do.” No you should put together a bad plan and you should implement it
because even if you fail in the implementation you’ll gather information and
then you can rectify the plan.
-Jordan Peterson
Math
Math problems are some of the hardest problems humans solve.
Besides the obvious things like practicing and learning more theory,
are there concrete techniques that can make us better problem solvers?
If you open a book on math problem solving, it will probably talk about heuristics.
Heuristics are relevant because they sit in between generating candidate
steps automatically (which requires no special teaching or memory aid) and
generating them uniformly at random or exhaustively (which is useless).
Heuristics may be general (see below) or
branch-specific (e.g. major counting techniques, inequalities cheat sheet).
They also may be more for information gathering or more for directly
taking a step towards a solution.
General heuristics:
- perform change of variables
- How to Solve It
- Schoenfeld, A.H. “Teaching problem-solving skills.”
- Ch. 1 of Larson, L. C. Problem-solving through problems.
- if you’re working from definitions try leveraging theory or vice versa
- name and conquer
Claude Shannon suggests
“try to restate [the problem] in just as many different forms as you can”.
T. Tao even says “The human
brain has got many different modes of thinking. So we have visual modes, we
have symbolic modes, we have modes where we are trying to fight some sort of
adversary. And by changing the language of your problem, you are activating
different areas of your brain.”
Comedian Lee Mack on generating ideas:
I was suddenly in a position where I could perform as many sketches as I could
think of in front of millions of people. But I didn’t have enough. So I went off
with my old college mate Neil Webster, and we locked ourselves away in a cottage
for three days. After a day of achieving nothing I decided that I’d had enough
of staring at the fireplace not knowing what to write about, so out of
frustration I picked up a magazine and told him to pick a random page number.
There were loads of different little articles on the page, so I asked him to
narrow it down to a corner. He said top left. It was an article about fishing. I
told him that we would both sit and write a sketch about fishing. So we did.
[…] Then we did it again, a new page, a new random corner. We found that about
every one in four mini-sketches had just about a funny enough premise, or key
joke, that it was worth exploring a bit more.
Similar techniques are described here.
However, in math if we’re solving a particular problem we want
to generate ideas in a more constrained manner.
Two possible methods are computer tools or bootstrapping by riffing
off of your own discoveries while making attempts towards a solution.
Computer tools for generating ideas:
With regards to bootstrapping, Richard Rusczyk’s top tip is “Do something … At some point you have to stop
staring and start trying stuff”.
Rusczyk elsewhere:
“Notice that we didn’t just sit and stare at the problem and wait
for it to solve itself. We have to add lines and variables so we can build
equations. Don’t expect to just memorize formulas and bash geometry problems.”
- You can’t write piano music all in your head, you have to press some keys to
help prompt ideas. in math, paper is the piano: write stuff down. this can be
thought of as freeing mental RAM.
- When deciding whether to try something or not, factor in not just how likely it is to solve the problem in one step but also the fact that the process of trying it may help you generate further ideas
Beyond
The “Build-Measure-Learn” loop in startup strategy is a lot like math problem solving
in that it says you don’t have to start with the complete solution, and data
generated by exploring the implications of an idea can help find further ideas.
See also https://longform.asmartbear.com/posts/extreme-questions/ for some heuristics
Does problem solving training in one domain improve problem solving ability in another domain? Cognitive psychology finds that cross-domain transfer is not automatic. Trinchero, R.,
“Chess Training and Mathematical Problem-Solving” (2016) says
The results suggest that chess practice can enhance problem-solving abilities in children, but only if chess training conveys problem-solving heuristics to pupils.
2021-Jan-18
The Three Character Classic is a 13th century Chinese text with three
characters per line which is traditionally read by children.
Below is an excerpt from the 1812
translation
by Robert Morrison, Presbyterian missionary and author of the first
Chinese-English dictionary.
Chung-ni [another name for Confucius] once called a boy of ten years of age
his instructor; for, of old, even perfect and wise men learned diligently.
Chao, when he held the office of Chung-ling, read Sun-yu. Though filling so
high a situation, he yet learned diligently – so much so, that he never laid
the book out of his hand.
In the time of the emperor Sung, Lu-wen-shu was constantly looking over the
books engraven on leaves.
Wu-yao made leaves of the reed bamboo, by paring it thin. Though he did not
possess books [as we do], he exerted himself in the pursuit of knowledge.
Sun-king suspended his head by its hair to the beam of his house, to prevent
his sleeping over his books.
Su-tsin pricked his thigh with an awl, to prevent his sleeping.
Those persons, though not taught, of themselves rigorously pursued their
studies.
Che-yin, when a boy, being poor, read his book by the light of a glow-worm
which he confined. And Sun-kang, in winter, read his book by the light reflected
from snow. Though their families were poor they studied incessantly.
Chu-mai-chin, though he subsisted by carrying fire-wood round the town to sell,
yet carefully read his book. At last he became capable of, and filled a public
office.
Li-mie, while watching his cattle in the field, always had his book at hand,
suspended to the horn of a cow. These two persons, though their bodies were
wearied by labor yet studied hard.
Su-lao-tsiuen, at the age of twenty-seven years began to exert himself, and
read a great many books. He, when at that age, repented of his delay: you,
a little boy, should early consider.
Leang-hao, at the age of eighty-two, was permitted to answer the emperor in
his palace, and was placed at the head of all the literati. In the evening of
life his wishes were fulfilled, and all spoke of his extraordinary learning.
You, a little boy, ought to determine to pursue your studies.
Yung, at eight hears of age could recite the Odes. Li-pi, at seven years of age
could play chess. These clever and studious boys were called by everyone
wonderful. You, youths, ought to imitate them.
Tsai-wen-ki could play a stringed instrument. Sie-tao-wen could sing well.
These ladies were clever. You, who are a gentleman, ought at an early time of
life, to perfect that which is suitable.
Chin-tung, a remarkable lad, was raised by the emperor to fill the office of
Ching-tsi. He, though a youth, was made a public officer. Do you, youths,
exert yourselves to learn, and you may arrive at the same. Let all who make
learning their pursuit be as those persons whom we have mentioned.
It is natural for a dog to watch at night, and for a cock to crow in the
morning; if anyone does not learn, how can he be called a man?
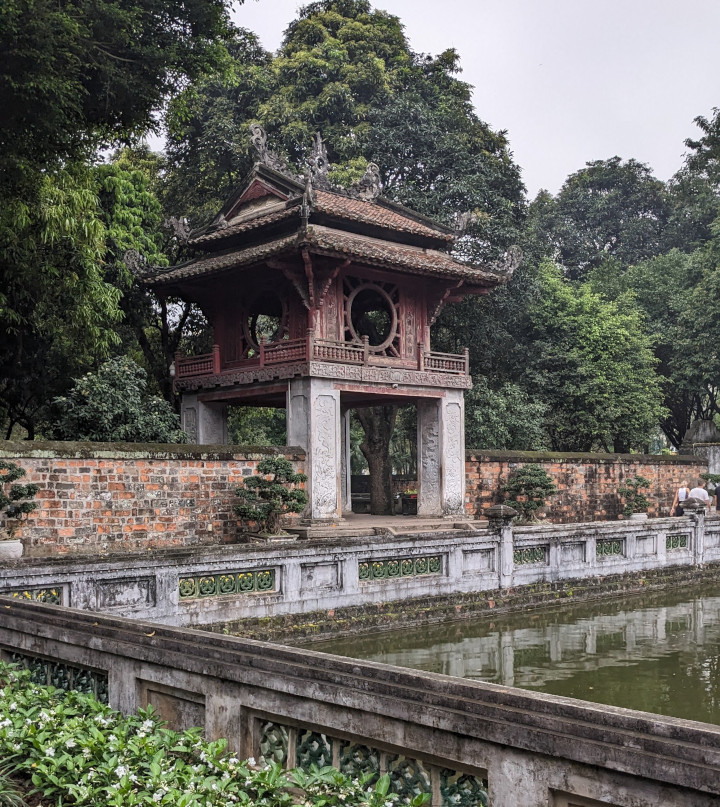 (Above: In the Temple of Literature in Hanoi.)
2020-May-22
Building on the framework in Comment ranking formulas,
if we add a new positive integer parameter called max_unique_comments, and we say that new comments are drawn uniformly at random from the set of unique comments with cardinality max_unique_comments, now users’ experiences with a comment depend on comments they’re previously seen. Using the Modified Bayes scoring system, we see the following results.
Assume the comment section lasts for 24 hours, there are 10 visitors per hour, and the probability that a visitor makes a comment is 0.1.
If max_unique_comments is 12:
- If duplicate comments are removed immediately, the average number of upvotes per visitor is 0.65
- If users downvote any comments they’ve seen before, the average number of upvotes per visitor is 0.62
- If users downvote any duplicate comments they see that don’t have the highest difference upvotes - downvotes, the average number of upvotes per visitor is 0.63
If max_unique_comments is 18:
- If duplicate comments are removed immediately, the average number of upvotes per visitor is 0.73
- If users downvote any comments they’ve seen before, the average number of upvotes per visitor is 0.70
- If users downvote any duplicate comments they see that don’t have the highest vote difference (upvotes - downvotes), the average number of upvotes per visitor is 0.71
So in conclusion: There is value in removing duplicates manually, not just leaving it up to the voting system.
Code: https://gist.github.com/andrew222651/cc32d857d9078f38a7b4c4b70c74ff51
2020-May-21
Comments on social sites have to be sorted somehow.
How do big platforms do it – is it some complicated mix of
recommender systems,
learning-to-rank algorithms,
Markov decision processes,
neural networks, and
learning automata?
Well, maybe in some cases
but often it’s just a simple formula.
In this article we put the formulas used by Hacker News, YouTube, and
Reddit, along with a few alternatives, to the test, using virtual comment
section simulations.
Spoiler alert: YouTube does not do well.
The simulation model
240 visitors arrive at equally spaced increments over a 24 hour period.
Each visitor is randomly assigned as a commenter (10%) or a voter (90%).
Commenters leave a single comment, which gets a randomly assigned quality
category: great (10%), mediocre (80%), or stinker (10%).
Great comments have a high probability of receiving upvotes and a low
probability of receiving downvotes;
stinkers are the reverse;
and mediocre comments have a low probability of receiving any votes.
Voters, on the other hand, see the top-ranked comment and vote according
to its probabilities.
At this point they stop reading or keep going based on a probability that
depends on the vote they just gave (0% for upvotes, 50% for downvotes, 15% for
non-votes).
If they don’t leave, they see the next-ranked comment and the process continues
until they finally do leave or they read all the comments.
When the simulation concludes, we log the average number of upvotes per
visitor which we use as our utility function.
See Python source code
for full details.
Of course this is not a perfect model of every comment section.
These parameter values will not always be accurate, although I did play around
with e.g. the commenter/voter ratio
and I got basically the same final conclusions.
Realistically the rate of visitors may vary over time.
A voter’s probability of leaving after a certain comment conditional on the
most recent (non-)vote may also depend on how many comments they’ve already
read.
Comment threads are not represented here.
Vote probabilities may change over time.
Et cetera, et cetera.
Here we use the following symbols
- Number of upvotes received so far: \(n_{+}\)
- Number of downvotes received so far: \(n_{-}\)
- Age of comment, in hours: \(h\)
All ranking methods in our analysis rank comments by scoring each comment
and sorting in descending order.
The scores are determined by the formulas below.
Starting with the basics, we have the ratio
\((n_{+} - n_{-})/(n_{+} + n_{-})\)
and the difference \(n_{+} - n_{-}\), a.k.a. the number of net upvotes.
We don’t expect these to be optimal but they’re useful baselines.
Another version of the ratio is
\(n_{+}/(n_{+} + n_{-})\) which performs similarly.
For testing purposes, we have the random ranking which is, well, just
random, and the upvote probability ranking which ranks according to the true
upvote probability.
Reddit’s algorithm, detailed here,
is a frequentist method for estimating the true voting probabilities
based on \(n_{+}\) and \(n_{-}\).
The Bayesian
version of this is what we’ll call the Bayesian average: the same as
ratio but we imagine that a few extra “phantom” votes have been cast, say 3
downvotes and 3 upvotes.
Hacker News roughly
uses the formula \((n_{+} - n_{-}) / (h+2)^{1.8}\),
which is like ratio, if we interpret the denominator \((h+2)^{1.8}\)
as an estimate of the number votes cast.
In fact, this denominator is probably more naturally thought of as an
estimate of the number of votes cast including implicit non-votes.
Non-votes (with a value of 0) would not impact the numerator.
To get a sense of how the simulations look, here are the comments as presented
to the 240th visitor from one run using the Hacker News scoring formula:
| \(h\) |
Upvote probability |
Downvote probability |
\(n_{+}\) |
\(n_{-}\) |
HN score |
| 7.9 |
0.671 |
0.324 |
47 |
5 |
0.657 |
| 14.2 |
0.671 |
0.076 |
82 |
3 |
0.515 |
| 21.9 |
0.496 |
0.14 |
110 |
10 |
0.324 |
| 23.3 |
0.434 |
0.051 |
72 |
12 |
0.174 |
| 8.9 |
0.162 |
0.03 |
8 |
0 |
0.094 |
| 14.1 |
0.112 |
0.054 |
12 |
3 |
0.060 |
| 10.9 |
0.184 |
0.058 |
6 |
0 |
0.059 |
| 5.1 |
0.151 |
0.008 |
2 |
0 |
0.058 |
| 12.9 |
0.226 |
0.049 |
6 |
0 |
0.046 |
| 15.0 |
0.114 |
0.061 |
10 |
6 |
0.024 |
| 7.3 |
0.021 |
0.009 |
1 |
0 |
0.017 |
| 13.4 |
0.071 |
0.008 |
1 |
1 |
0.0 |
| 5.2 |
0.489 |
0.038 |
0 |
0 |
0.0 |
| 3.6 |
0.151 |
0.041 |
1 |
0 |
0.0 |
| 1.0 |
0.579 |
0.087 |
0 |
0 |
0.0 |
| 0.7 |
0.047 |
0.024 |
0 |
0 |
0.0 |
| 21.7 |
0.158 |
0.222 |
19 |
20 |
-0.003 |
| 20.7 |
0.048 |
0.017 |
1 |
3 |
-0.007 |
| 10.4 |
0.055 |
0.044 |
1 |
2 |
-0.010 |
| 11.3 |
0.041 |
0.027 |
0 |
2 |
-0.018 |
| 19.5 |
0.104 |
0.166 |
5 |
10 |
-0.019 |
| 5.4 |
0.045 |
0.604 |
1 |
3 |
-0.054 |
YouTube also uses a formula that
involves the age of the comment.
Their system additionally factors in the user’s lifetime ratio, which
for our tests we set to 0 as if all users are new.
Lastly, let’s consider how we might modify the Bayesian average to take
time into account.
To make new comments more visible we’ll make the phantom votes all upvotes
at first, then asymptotically reduce them to non-votes.
We’ll also switch to a denominator similar to the Hacker News formula’s in
order to estimate non-votes.
This yields the modified Bayes formula
\[\frac{n_{+} - n_{-} + n_p / (h+1)}{n_p + h},\]
where \(n_p\) is the number of phantom votes.
We use the value \(n_p=7\) in the simulations.
Ranking the rankings
I did enough simulation runs (1000-20000) with each formula
to be pretty confident about how they compare.
Without further ado, voila:
| Ranking algorithm |
Average number of upvotes per visitor |
| Upvote probability |
0.978 |
| Modified Bayes |
0.916 |
| Hacker News |
0.899 |
| Bayesian average |
0.878 |
| Difference |
0.848 |
| Reddit |
0.836 |
| Ratio |
0.813 |
| YouTube |
0.644 |
| Random |
0.607 |
So YouTube is marginally better than random, Reddit is worse than the simple difference, and
Hacker News is the only one of the three better than Bayesian average.
Disappointing but also plausible. How generalizable are the results?
As always, more work required…
2020-Apr-12
Mainland Canada extends south to a latitude found in California
There’s a piece of France in between Nova Scotia and Newfoundland
Victoria, BC has a “warm-summer Mediterranean climate”
like Porto, Portugal and Cape Town, South Africa.
Canada’s most picturesque spot is Lake Louise.
The Newfoundland accent on Fogo Island is so strong it just sounds like an Irish accent.